
Extreme DRY: When ‘Don’t Repeat Yourself’ Repeats All Your Other Problems
Or: How the Engineering Principle You Learned First Quietly Strangles the Architecture You’re Trying to Build
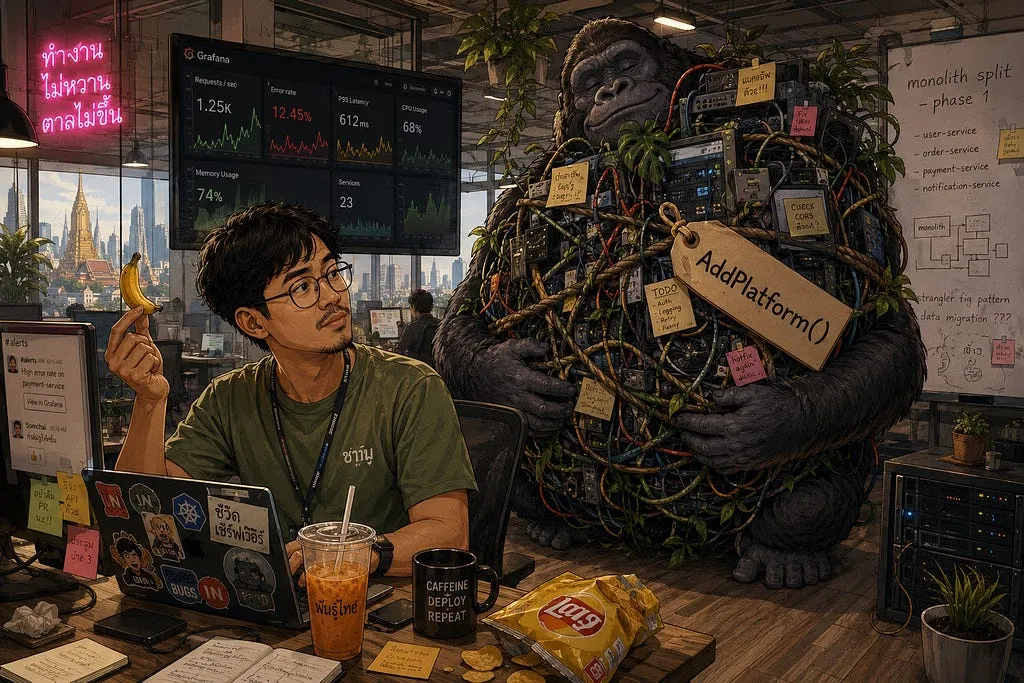
It was 3:14 on a Tuesday afternoon and the war room on level 7 was already cold from the air-con working too hard. The VP was standing behind Somchai’s chair, one hand on the back of the chair, the other pointing at the stack trace on the wall monitor. “Why.” Not a question, a verb. “Why is the service not starting?” Somchai’s cursor was on a single line of Program.cs, builder.Services.AddPlatform(), and the only honest answer he had was I don't know, it's a black box, the breakpoints don't hit. He didn't say it. He said nothing. Across the room, Namfon from the platform team had her laptop open on the table — the fourth war room she'd been pulled into that day. She'd written most of AddPlatform() herself. She knew exactly which line was failing. What she didn't know — what nobody in the room knew — was why a decision made two years ago, before she'd even joined the team, had made her the only person who could answer the question.
That moment — a senior engineer with no answer, a VP with no patience, and a platform engineer being held accountable for an architectural choice made before her time — is the whole post.
We built that black box. We built it on purpose. We built it because every engineer learns DRY before they learn anything else about design, and by the time they have five years’ experience, Don’t Repeat Yourself isn’t a principle anymore — it’s a reflex. And that reflex, taken to its logical extreme, builds systems that nobody can change.
I Wanted a Banana and Got a Gorilla Holding the Banana, and the Rest of the Jungle Too
Let me tell you about a pattern I’ve seen up close. A team had just finished splitting a large monolith along business-domain lines — booking, payment, search, all the pieces you’d expect. That part went well. The bounded contexts were thoughtful, the services were owned by the teams who actually understood the business.
Then came the question of cross-cutting concerns. Logging, tracing, authentication, configuration loading, the middleware pipeline, attribution, feature flags. Things that — by definition — every service needs.
The well-intentioned answer: a platform library that packaged all of it together. One NuGet package. One method to call in Program.cs:
builder.Services.AddPlatform();
That was it. Beautiful. Every new service got logging, tracing, auth, middleware, attribution, and config in one line of code. No team had to think about plumbing. No team had to duplicate setup. No team had to reinvent the wheel. Pure DRY, applied at the platform layer.
It looked like the right answer at first.
Then the problems started.
Problem one: nobody could debug it locally. When something went wrong inside AddPlatform() — and things did go wrong — engineers couldn't step through the initialisation to find the issue. The platform was a black box with one entry point and a hundred internal moving parts. Every failure became a Slack escalation to the platform team: "I added the library and my service won't start, what's happening?"
Problem two: the HTTP pipeline was inside the platform. This was the killer. Business logic that had to live in the HTTP request pipeline — attribution rules, request enrichment, certain auth flows — was buried inside the platform library. Which meant any team that needed to change attribution couldn’t just change it in their service. They had to file a request with the platform team, wait for the platform release, then upgrade. The team that owned the business outcome didn’t own the code that delivered it. The platform team had become the bottleneck the monolith split was meant to remove.
Problem three: the gorilla and the jungle. I wanted a banana — just experimentation, say, A/B testing for a new admin tool. What I got was a gorilla holding the banana, and the rest of the jungle too. The experimentation library pulled in the translations library (but the tool was English-only and would stay that way), which pulled in affiliate ID tracking for commissions (but the site doesn’t sell anything), which pulled in currency conversion (no prices on the page), which pulled in the user-segmentation library (no users — it’s an internal admin tool). All of it loaded. All of it initialised. All of it part of the dependency graph on every cold start. The shared library was technically optional in pieces, but operationally it was all-or-nothing.
The team had eliminated duplication. They had built one canonical platform. Every service was set up identically with one line of code. By every conventional measure of DRY-ness, this was a triumph.
It was also a slower way to ship business changes than the monolith had been.
The lesson, in one line: we built a monolith out of “shared concerns” and called it a platform. The decomposition the business needed — independent services, owned end-to-end by their teams — was undone at the platform layer. We removed one kind of duplication and replaced it with one kind of coupling. The coupling was worse.
“Duplication is far cheaper than the wrong abstraction.”* — Sandi Metz, The Wrong Abstraction (2016)*
That works because it inverts the engineer’s instinct. The gut says duplication is expensive and abstraction is free. Metz priced both, and the ratio is the opposite of what most engineers assume. The platform library is the institutional version of the same mistake — built by good engineers, for good reasons, and slowly strangling the architecture it was supposed to enable.
The interesting epilogue: this isn’t a new mistake. Microsoft learned it years ago and rebuilt their entire .NET ecosystem around the lesson. The modern .NET pattern — IServiceCollection, individual AddLogging(), AddAuthentication(), AddTracing() methods exposed as separate concerns through extension methods, with each piece testable and replaceable in isolation — is exactly the answer. The platform team's mistake was to wrap all of that back up into a single AddPlatform() call. Modularity that was hard-won at the framework level got bundled away at the application level.
DRY Is a Dimension, Not a Rule
Here’s where most teams go wrong, and where the rest of this post lives.
The reason DRY fails so badly in practice isn’t that the principle is wrong. It’s that we taught it as a rule. Rules are binary — do this, don’t do that. And once a heuristic gets encoded as a rule, the conversation about when and how much stops happening. You can see this in code review every day: “this is duplication” lands as if it were “this is a bug.” It isn’t. It’s a position on a dimension.
DRY isn’t a switch you flip. It’s a dial. And the engineering skill is knowing where on the dial your current context belongs.
At one extreme — call it 10 on the dial — every duplication gets extracted on sight. Every helper that might be reused gets centralised. Every two methods that look similar get unified into one with a parameter. The codebase has no surface repetition and looks, on paper, beautifully clean. This is where extreme DRY lives. It’s also where you get the BaseController with 30 constructor parameters, the platform library that became its own monolith, the HTTP endpoint built to save one line of date math, and the BFF that quietly stopped being a BFF.
At the other extreme — 0 on the dial — nothing is shared. Every team copies what they need. Every service has its own copy of the date library. Bug fixes happen in seven places. New engineers wonder what the difference is between FormatDate() and FormatDatev8(). This is the failure mode the original DRY principle was written to prevent, and it's still real — the answer to "extreme DRY" isn't "no DRY."
The skill is calibration. A small early-stage codebase with one team, one bounded context, and tight cohesion can sit comfortably around 7 or 8 — extract aggressively, refactor often, your domain is still coherent and your shared code is going to evolve together anyway. A mature multi-team architecture, where teams own different services on different release cycles, needs to sit much lower — maybe 3 or 4 — because every shared abstraction is now a coordination cost.
Most engineering teams I’ve worked with have one number they apply everywhere. That’s the bug. The codebase isn’t one context; it’s many. The number that’s right for a freshly-extracted service in its first month is wrong for a five-year-old shared library used by twelve teams.
The original DRY principle hinted at this. Hunt and Thomas, 1999: “Every piece of knowledge must have a single, unambiguous, authoritative representation within a system.” The word knowledge is doing the work — not text, not lines. Two pieces of code that look identical might be expressing the same piece of business knowledge (and so belong together), or they might be two independent calculations that happen to look alike today and will diverge tomorrow (and need to stay apart). Reading the duplication correctly is part of where on the dial you place yourself.
The question that does the work isn’t “is this duplicated?” It’s:
“How far along the DRY dimension does this particular context call for, and where is this code right now?”
That’s a calibration question. It has a different answer for a startup MVP than for a service split out of a five-year monolith. It has a different answer for the booking domain than for cross-cutting infrastructure. It even has a different answer for the same codebase three years apart, because the codebase has changed and the team owning it has changed.
There’s no rule that gives you the answer. There’s only judgement informed by context.
This isn’t unique to DRY. It’s the same shape as every other “best practice” in software engineering:
There is no such thing as best practice. There is only adequate practice given the current context.
That’s the deeper claim, with DRY as the case study. Any heuristic, once it stops being a heuristic and becomes a rule, will be misapplied in the contexts where it doesn’t fit. The job of the senior engineer isn’t to enforce best practices. It’s to teach the team to read context and pick the adequate practice for the moment.
The Four Symptoms of Extreme DRY
You’ve seen these. You might be living in one right now.
a) The God Helper
A Utils class. A Helpers.cs. A common.ts. It started with three functions. It now has 47, including one called SanitizeString and another called SanitizeStringForDb, plus SanitizeStringForUrl, plus SanitizeStringV2, plus CleanString, plus TrimAndClean. Every team imports it. Every team has tried to refactor it and given up. Every change to it requires a review from someone who happens to remember which one strips the <script> tags and which one just lowercases.
The God Helper isn’t designed. It’s accreted. And every commit makes it harder to break apart, because every commit adds another caller.
b) The Christmas-Tree Parameter List
A function extracted from two near-duplicates. Then a third caller showed up that’s almost the same — but needs one tweak. Add a boolean parameter. A fourth caller — add another. The function’s signature now reads like a feature flag config. Each parameter exists because the function should have been left as duplicated code two years ago.
“With four parameters I can fit an elephant. With five, I can make him wiggle his trunk.”* — John von Neumann (attributed)*
The function with five parameters isn’t a function. It’s a mechanism for hiding the fact that you have five different functions. Sandi Metz documented this exact failure mode in The Wrong Abstraction: programmer A extracts the shared method; programmer B comes along, needs a slightly different shape, and instead of un-extracting, adds a parameter. Then C does the same. The shared method becomes a parameter zoo, and every caller pays the cost of all the others’ edge cases.
c) The Inheritance Hierarchy Built on Surface Similarity
The canonical shape: a BaseController that every other controller in the codebase inherits from. It starts as a sensible idea — a few shared concerns, request logging, auth checks, error handling. Then someone adds dependency injection for the things "every controller needs." Then someone adds the next thing, and the next. The constructor parameter list grows. The class grows.
I worked with one of these once that reached 1,500 lines of code and 30 constructor parameters. Every controller in the system inherited from it, which meant every controller had to accept all 30 dependencies — including ones that needed three of them and could have been instantiated in 20 lines of code. It was the jungle, and you got it every time you wanted the banana. Same disease as the platform library, different organ: the platform bundled at initialisation, the BaseController bundled at inheritance.
The deeper failure is the same shape: “shared behaviour” in the base class often turns out to be eight protected virtual methods that each subclass overrides differently — at which point the base class isn't providing behaviour, it's providing a template that the subclass has to fill in. Which is what duplication was, just with more ceremony. The "DRY" gain is fictional; the cost — every test now has to construct 30 dependencies, every new controller has to understand the whole inheritance hierarchy, every change to the base class is a release coordination problem — is real.
d) The Premature Shared Library
Two teams notice they’re writing similar code. They create Company.Common. Within six months, neither team can change the library without coordinating with the other. Within a year, a third team avoids depending on it because of the coordination tax. Within two years, the library has three competing maintainers and a Confluence page nobody reads.
The library was created to reduce duplication. The cost it introduced — coordination, versioning, ownership disputes, the slow drift of “who is this library actually for?” — was never priced into the decision. Because in DRY-as-rule, that cost is implicitly zero.
It isn’t.
The Coupling Cost That Nobody Prices
Engineers fight duplication because they can see it. The cost is visible: extra lines, extra tests, more places to fix a bug. The cost of coupling is invisible — until it shows up in a place that has nothing to do with where the abstraction was made.
Let me show you what I mean with a short story.
I worked on a system that sent a reminder email seven days before a scheduled date. The sending mechanism was a Kafka consumer with its own database for state — it tracked which reminders had been queued, which had been sent, the standard stuff. The data the email referenced lived elsewhere, in the primary application.
The product team wanted to add a button in the UI: once the reminder email had been sent, the user should be able to click through and view the underlying data. Simple enough.
Here’s where it gets interesting. The condition for showing the button was: “the email has been sent” — which is just “today’s date is within seven days of the scheduled date.” One line of code in the UI. Compute the difference. If it’s ≤ 7 days, show the button. Done.
That’s not what got built.
What got built was an HTTP endpoint on the Kafka consumer service, exposing its internal state, so the UI could call it and ask “has the email been sent for this user?” The UI called the endpoint. The endpoint queried the consumer’s database. The database returned the row. The UI parsed the response and decided whether to render the button.
To avoid one line of duplicated date-math, the team:
- Added a new HTTP surface to a service that didn’t have one before- Exposed the consumer’s internal state to an external caller- Introduced a network call to answer a question the UI could have answered locally- Created a runtime dependency from the UI to a backend service whose sole purpose was to be an asynchronous, fire-and-forget email sender- Made the UI’s ability to render a button depend on the Kafka consumer being available The seven-day window wasn’t going to change. The business logic wasn’t going to drift. The “single source of truth” the team was protecting was a calendar — the calendar. The same calendar both sides already had access to.
This is the coupling cost made visible. The team wasn’t lazy and they weren’t stupid — they were following the rule they’d been taught: don’t duplicate logic. What they hadn’t been taught was the question: is the cost of duplicating this one line higher or lower than the cost of building an entire new integration? If they’d asked it for thirty seconds, the answer would have been obvious.
So what are the actual costs DRY-as-reflex never accounts for?
Change amplification. A modification to a shared abstraction touches every caller. If your caller list is two, that’s fine. If it’s two hundred, that’s a release coordination problem disguised as a code change.
Cognitive load. To understand a method that’s used in eight contexts, you have to understand all eight. The “shared” code stops being a black box and starts being a piece of shared mental state. Local reasoning — the ability to understand a piece of code by reading the file — dies.
Decomposition resistance. This is the big one. Every shared abstraction across a candidate service boundary is a chain that has to be cut before the split can happen. The more chains, the higher the activation energy for the change you actually need to make. We’ll come back to this one.
Runtime dependency creep. This is the one the email story illustrates. Coupling isn’t just a code-level concept — it’s an operational one. Every HTTP call you add to “share” a piece of state is a new failure mode at runtime. The button could have rendered based on a local date calculation that couldn’t fail. Instead, its existence now depended on a network call to a service designed for asynchronous message processing. If the consumer was down or slow, the button wouldn’t render.
When you DRY two pieces of code together, you’re not just removing duplication — you’re adding an edge to the dependency graph of your system. That edge has its own cost in flexibility, coordination, decomposition difficulty, and runtime availability. The cost is often higher than the cost of the duplication. But it’s invisible until the day you need to move one of those nodes, or one of them goes down at 3 AM.
Here’s the conversation worth having. Next time someone wants to extract:
“What happens the first time these two callers need to behave differently? Right now they look the same, but they live in two different domains with two different futures. The moment the booking side needs a new currency rule and the reporting side doesn’t, we’ll add a flag. Then a second flag. Then a third caller shows up. Two years from now this is a method with seven parameters that nobody can read, and changing any one of them risks breaking five things. Or we leave it duplicated, and when the booking side needs a new rule, it changes one file. Which version of the codebase do you want to maintain?”
The argument the script makes is one that doesn’t go away when you change where the code physically lives: shared code forces shared shape. Two callers that use the same function are constrained to keep behaving the same way, or the function grows parameters to accommodate the differences. That cost lives in the design, not in the build pipeline. A monorepo doesn’t fix it. It just makes it easier not to notice.
The math isn’t always this clean. The act of doing it changes the conversation from “good practice vs lazy” to “this cost vs that cost.” Which is the conversation you actually want to be having.
Stable Contracts: When Slow Is the Point
This is the post’s most counterintuitive argument, and probably the most important one.
When engineers argue against splitting a monolith, the argument often takes this form: “If we split, we’ll need a shared library, and that’ll slow us down.” True. And: that slowness is often what you want.
A contract that moves slowly between two systems is a feature. The contract is what stops a change on one side from breaking the other by accident. The slowness is intentional friction — and intentional friction is the mechanism by which the contract gets respected. The trouble is that “removing friction” sounds, in every engineering culture I’ve ever worked in, like an unambiguous win. It isn’t. Some friction is the architecture doing its job.
Let me tell you about the BFF that stopped being a BFF.
I worked on a system with a backend and three clients — web, Android, and iOS — sitting behind a BFF (backend-for-frontend). Standard pattern: the BFF’s job is to maintain a stable contract for the clients while the backend evolves at its own pace. The mobile apps especially needed it; iOS and Android both have long-tail version distributions, and any breaking change in the backend’s payload propagates to every app version still in the wild.
Every backend change required a corresponding BFF change. That’s how the system was designed. It also felt — to the engineers shipping every day — like an obvious inefficiency. “We’re touching two repos for one change.”
Someone came up with what sounded like a great idea: publish the backend’s schema at runtime and have the BFF dynamically map its response types from the live backend schema. “Now we only have to update the backend. The BFF picks up the change automatically.” Fewer pull requests. Fewer commits. Velocity up.
Ignoring the fact that the BFF’s literal job is to maintain a stable contract.
A few months after the project shipped, one of the backend engineers showed me a report he was proud of. It mapped which iOS versions in the wild were using which fields of his backend contract. He was excited — it would let him plan field deprecations more easily. “I can see when nobody’s using the field anymore.”
My jaw dropped.
That report should never have existed. The backend engineer should not have been able to see iOS versions at all — that’s exactly what the BFF was supposed to hide. The friction the team had “removed” was the friction that decoupled the iOS release cycle from the backend release cycle. The BFF was still there in the codebase. Architecturally, it had ceased to exist. The backend engineer now had end-to-end visibility into the mobile clients, and was happily optimising past a boundary that no longer functioned as one.
We hadn’t sped anything up. We’d merged a four-system architecture into one tightly-coupled blob with extra hops. The deprecation report wasn’t a triumph; it was the failure mode showing itself in the most well-intentioned way possible. The team had built a tool to make the wrong work easier.
The principle:
The right amount of friction between two systems is whatever makes the cost of coupling them visible at the moment they’re being coupled.
Too little friction → developers couple things accidentally and discover the cost later (the BFF story, and most monorepos in my experience). Too much friction → nobody integrates anything and you have a coordination crisis. The right friction is intentional — chosen, named, defended — and it’s the friction that prompts a conversation.
Linus Torvalds has been shouting “WE DO NOT BREAK USERSPACE!” at kernel maintainers for thirty years. That’s a stable contract. It costs the kernel team enormous ongoing energy. They pay it on purpose. The slowness is what makes the kernel a thing the rest of the world can build on. The contract isn’t a bug. It’s the whole point.
If you’ve ever read 6 Golden Rules for Library Development, this is where it cashes out — the discipline of non-breaking changes is what makes slow contracts liveable. Without it, the slowness is just annoying; with it, the slowness is protective.
When Sharing Is Actually Right
The post can’t just be “stop sharing things.” That would be as bad as “share everything.” So here’s how to read the cases where sharing is the right call.
Strong candidates for sharing — places where the signal is genuine, unifying knowledge:
Domain primitives that are foundational to the business. A Money type. A BookingId. A Currency enum. These are ubiquitous language, in Eric Evans' sense. They don't change often, and when they do, every consumer should see the change.- Cross-cutting infrastructure with a stable, narrow contract. Logging, tracing, auth. But — and this matters — the shared thing is the interface, not the implementation. See Managing Dependency Conflicts in Library Development for the abstractions-library pattern.- Encoded business rules that are legally or contractually identical everywhere. Tax calculation. Regulatory compliance. PII redaction. If the business says “this is the rule,” there’s exactly one rule. Weak candidates for sharing — places where the signal is accidental similarity:
Anything that “looks similar today” but is owned by different teams. Different owners → different velocities → different futures. The similarity is a snapshot, not a structure.- Anything that crosses a service or domain boundary you’re actively trying to enforce. Sharing across the boundary undoes the boundary.- Anything that’s been DRY-ed up and immediately needed a flag parameter. That’s the signal that you’ve coupled two pieces of knowledge that wanted to diverge. The question that does the work isn’t binary. It’s calibrated:
“Given this code, this team, this service boundary, and this rate of change — where on the DRY dimension does this belong, and how confident am I that it belongs there?”
A Money type owned by one platform team across a stable business: high on the dial. The expected lifetime is years, the consumers are many, the contract is stable, the knowledge is genuinely singular. Extract it.
A “shared helper” between two teams that just split out of a monolith and are still discovering their own shape: low on the dial. The expected lifetime of the similarity is months, the consumers are diverging, and the cost of locking them together now is the cost of preventing the divergence that was the whole point of splitting. Leave it duplicated.
The same code in the same team six years apart can call for different answers. That’s not a bug in the framework. That’s the framework.
A Sidebar: The Look of Shock
I’ve told teams, very casually, “just copy-paste it into the other repo.” You’d think I’d stood on their cat. “Copy. Paste?” The look of shock — like I was some kind of heretic.
That reaction is the whole problem. DRY has stopped being a heuristic for these engineers and become a moral framework. Copy-pasting isn’t a technical choice with trade-offs — it’s wrong, in the same register as not writing tests. Which means the conversation can’t happen on technical grounds, because the engineer isn’t on technical grounds. They’re defending a value.
The job of the senior engineer in that moment isn’t to win the technical argument. It’s to give the team permission to think technically — to name the value, separate it from the heuristic, and ask the actual question: what’s the cost of duplicating these eight lines versus the cost of coupling these two services? Once the question is on the table, most engineers can answer it.
It’s the asking that’s hard.
Too Much Doing, Not Enough Thinking
The real villain in this post isn’t DRY. It isn’t the engineer who reflexively extracts a helper. It isn’t the reviewer who demands deduplication on every PR. The villain is the absence of the conversation that should have happened before the keystroke.
The engineer who reflexively DRYs a two-line duplication isn’t being dogmatic — they’re being under-equipped. They never had the five-minute conversation about coupling cost. Nobody walked them through the rule of three. Nobody showed them Metz’s essay. They learned DRY as a rule from a textbook, and nobody taught them the second half.
The God Helpers, the Christmas-tree parameter lists, the BaseControllers with 30 constructor parameters, the platform libraries that became their own bottleneck — none of these are caused by bad engineers. They’re caused by too much doing, and not enough thinking.
“Premature optimization is the root of all evil.”* — Donald Knuth (paraphrasing Tony Hoare)*
The analogue holds: premature abstraction is the root of an awful lot of system-level evil. Both are caused by the same instinct — solving for an imagined future rather than the actual present. Both look like good engineering at the moment they happen. Both pay back over years.
The fix is unglamorous. It’s a conversation between two engineers with experience, before the extract-method shortcut gets used. Five minutes of “should we?” prevents five years of “how do we untangle this?” And the way you make those conversations cheap and frequent is by sharing knowledge — workshops, brown bags, design reviews that actually review design, senior engineers who teach by walking through trade-offs instead of just shipping the answer.
I run workshops constantly — internally at work and in the wider engineering community. The reason isn’t that workshops are a goal. It’s that they’re the cheapest mechanism humans have ever invented for the conversation that prevents the wrong abstraction. Five engineers in a room, an hour of their time, one shared mental model of why coupling has a cost. The ROI is enormous, and it’s underrated because the bug it prevents is the one that never gets written.
This is also the inverse of something I wrote about in Code Entropy: The Silent Killer of Engineering Velocity — copy-paste coding is an entropy source, yes. But copy-paste avoidance, taken to its extreme, is also an entropy source. Just a slower-acting one. Both are symptoms of the same disease: applying a rule without the conversation that turns it into judgement.
DRY failed because we made it a rule.
It isn’t a rule. It’s a dimension, and the engineering skill is knowing how far in either direction your current context allows you to go.
There is no such thing as best practice. There is only adequate practice given the current context.
Now, if you’ll excuse me, I need to go review a pull request. Someone on my team has extracted a helper that takes seven parameters, and I’m about to type a polite comment asking whether this helper is really one function or three pretending to be one. I’ll probably get it wrong the first time. I usually do. But the conversation is the point.