
The Automation That Isn’t: Why Your CI Pipeline Is Just a Very Expensive Reminder App
Or: How We Built Machines to Tell Humans to Do the Work Machines Should Be Doing
We need to talk about an uncomfortable truth hiding in plain sight across engineering organisations everywhere. We’ve spent years building sophisticated CI/CD pipelines, code review bots, and AI-powered analysis tools — and then configured them to send Slack messages asking humans to do manual work.
Let that sink in for a moment. We automated the asking. Not the doing.
As the management theorist Peter Drucker once observed, “There is nothing so useless as doing efficiently that which should not be done at all.” We’ve become remarkably efficient at building systems that efficiently remind people to do things inefficiently.
I stumbled across this pattern recently when reviewing a conversation about configuring a code review bot. Someone wanted the bot to remind developers to bump version numbers in merge requests. Fair enough — version management matters. But here’s the thing: the bot would leave a comment saying “please bump the version,” which a human would then need to read, acknowledge, and manually edit a file. The automation’s sole contribution was nagging.
When I suggested actually automating the version bump itself — having CI compute the appropriate version and apply it — the response was illuminating: “I find it easier to use plain English in a AI prompt instead of GitLab YAMLs.”
And there it is. The path of least resistance led us to build a reminder system when what we needed was an automation system. We took the hard part (setting up a bot to analyse code and post comments) and used it to avoid the easy part (incrementing a number in a file).
The Taxonomy of Fake Automation
After digging through configurations across dozens of repositories, I’ve found this anti-pattern everywhere. It manifests in several distinct flavours, each more insidious than the last.
The File Synchronisation Nagger
You’ve seen this one. A bot comments on your merge request:
“Please update ./openapi.json when fields are added.”
Or:
“Ensure you update BOTH opa/prod/data.yaml AND opa/non-prod/data.yaml.”
Or my personal favourite:
“Ensure that it aligns with the external_loyalty_transaction_enums table in the database.”
Think about what’s happening here. We’ve built automation sophisticated enough to detect that a change might require updates elsewhere. It can parse your code, understand the context, and determine that a synchronisation might be needed. And then, at the moment of maximum leverage, it… asks a human to go do it manually.
The basketball coach John Wooden had a saying: “Never mistake activity for achievement.” We’ve built systems with tremendous activity — analysing diffs, posting comments, creating threads — that achieve nothing except adding an item to someone’s mental to-do list.
The better way: If your system can detect that File A changed and File B needs updating, your system can update File B. OpenAPI specs can be generated from code annotations. Configuration files can be templated and rendered. Database schema documentation can be extracted automatically. If true synchronisation requires human judgment, then the bot should fail the build until the human makes a decision — not leave a polite suggestion that gets lost in a sea of review comments.
.NET: Swashbuckle generates your spec automatically from controllers, or use the built-in OpenAPI support in .NET 9+Kotlin/Java Spring Boot: SpringDoc OpenAPI examines your application at runtime and generates the spec from annotations with zero manual configurationSpec-first (all platforms): OpenAPI Generator generates server stubs and client SDKs for Java, Kotlin, C#, and dozens of other languages as part of your CI pipelineConfiguration files can be templated and rendered. Database schema documentation can be extracted automatically. If true synchronisation requires human judgment, then the bot should fail the build until the human makes a decision — not leave a polite suggestion that gets lost in a sea of review comments.
For version bumping specifically, the pattern is even simpler. Instead of a bot commenting “please bump the version in gradle.properties,” have CI calculate the version from semantic commit conventions and apply it automatically. Here’s a GitHub Action that determines the version bump from PR title prefixes:
.github/workflows/version.yml
name: Auto Version on: pull_request: types: [opened, edited, synchronize] jobs: version: runs-on: ubuntu-latest steps: - uses: actions/checkout@v4 with: fetch-depth: 0
  - name: Calculate version from PR title
    run: |
      # Get latest semver tag
      LATEST_TAG=$(git tag -l "v*.*.*" --sort=-v:refname | head -n1 || echo "v0.0.0")

      # Parse current version
      VERSION=${LATEST_TAG#v}
      MAJOR=$(echo $VERSION | cut -d. -f1)
      MINOR=$(echo $VERSION | cut -d. -f2)
      PATCH=$(echo $VERSION | cut -d. -f3)

      # Determine bump from PR title prefix
      PR_TITLE="${{ github.event.pull_request.title }}"
      case "$PR_TITLE" in
        BREAKING*) MAJOR=$((MAJOR + 1)); MINOR=0; PATCH=0 ;;
        FEATURE*)  MINOR=$((MINOR + 1)); PATCH=0 ;;
        PATCH*)    PATCH=$((PATCH + 1)) ;;
        *) echo "::error::PR title must start with BREAKING, FEATURE, or PATCH"; exit 1 ;;
      esac

      echo "NEW_VERSION=$MAJOR.$MINOR.$PATCH" >> $GITHUB_ENV

  - name: Update version file
    run: |
      echo "version=$NEW_VERSION" > gradle.properties
      git config user.name "github-actions[bot]"
      git config user.email "github-actions[bot]@users.noreply.github.com"
      git add gradle.properties
      git commit -m "chore: bump version to $NEW_VERSION" || echo "No changes"
      git pushThe same pattern works in GitLab CI — we use a reusable CI template that calculates semver from MR titles and creates releases automatically. The human’s only job is to prefix their PR title correctly; everything else happens without intervention.
The Lint Comment Cascade
This one is particularly pervasive. Your CI pipeline runs SwiftLint, ESLint, or whatever flavour of static analysis your stack prefers. It finds seventeen violations. And then it… posts seventeen comments on your merge request telling you what to fix.
I’ve seen configurations that will literally post “LINTING FAILED — Quick Fix Available. Run pnpm lint-changed --fix locally" as a comment. Read that again. The automation knows exactly how to fix the problem. It even knows the command. It just refuses to run it.
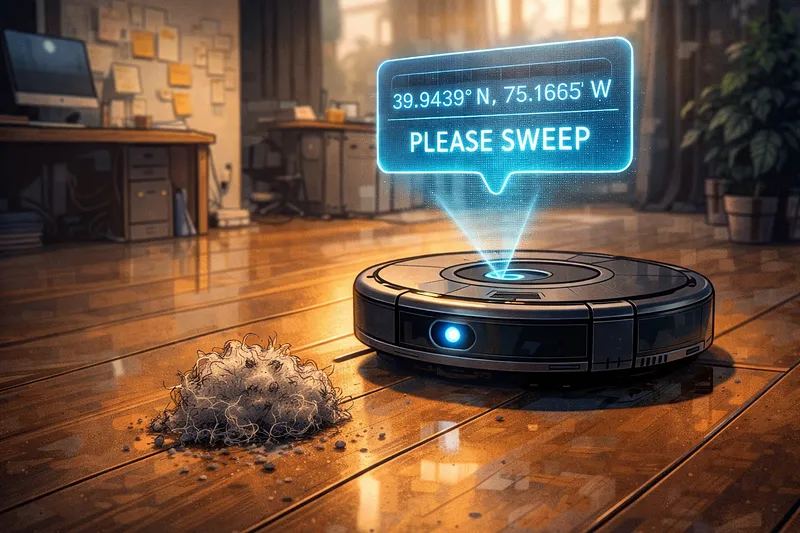
This is like having a robot vacuum that rolls up to a dust bunny, takes a photo, sends you a push notification with the coordinates, and then powers down. “Dirt detected at coordinates 4.2, 7.8. Please sweep.”
The better way: Fix issues before they ever reach CI. Most modern IDEs can auto-fix linting violations on save — the developer never sees a warning, the code is just correct. This is the real automation: invisible, instant, and requiring zero human intervention.
JavaScript/TypeScript: The ESLint extension for VS Code or IntelliJ’s built-in ESLint support can auto-fix on save with a single settings changeC#/.NET: Rider’s built-in reformat on save or CSharpier for VS Code and Rider will format your code the moment you hit saveKotlin: The ktlint IntelliJ plugin formats code on save, or use detekt with ktlint integration for comprehensive analysisThe key is making sure your whole team has these plugins installed. Both major IDEs support committing configuration files that prompt developers to install the right extensions when they open the project:
IntelliJ/Rider: Add required plugins via Settings → Build, Execution, Deployment → Required Plugins. This creates an .idea/externalDependencies.xml file — commit it, and teammates will be prompted to install missing plugins when they open the project.VS Code: Create a .vscode/extensions.json file with a recommendations array listing extension IDs. When teammates open the workspace, VS Code will prompt them to install the recommended extensions.If you want a safety net in CI, you can still run the linter there — but have it auto-fix and commit the changes back to the branch rather than posting comments. Some teams find CI commits confusing (“who made this commit?”), which is why the IDE plugin approach is cleaner: the fix happens at the source, in the developer’s hands, before the code ever leaves their machine.
For issues that genuinely can’t be auto-fixed, fail the build rather than commenting. A failed build demands action. A comment becomes archaeology — buried under other comments, forgotten until someone notices the unresolved thread weeks later.
The MR Metadata Police
“MR title must include a Jira ID.” “Please add reviewers to this PR.” “This PR does not refer to a release milestone.” “The mandatory checklist for contributor is not complete.”
These messages appear hundreds of times a day across large organisations. Each one requires a human to stop what they’re doing, context-switch back to the merge request, and perform a manual edit that could have been automated or enforced differently.
The comedian Jerry Seinfeld once described his creative process: “I look for the path of least resistance that still gets the job done.” Our automation systems have found the path of most resistance — the one that interrupts the most humans the most frequently while contributing the least actual value.
The better way: Parse the branch name or commit message and extract the Jira ID automatically (You’d be supprise how many people just do this by default). Auto-assign reviewers based on code ownership files or recent contributors, or do something fancy with history of area they’ve touched. Set milestones based on target branches. For checklists that genuinely require human attestation, make them a blocking merge check rather than a drive-by comment that someone can ignore.
The AI Code Review That Reviews But Doesn’t Act
This is the newest and perhaps most ironic variant. We’ve deployed large language models — systems capable of understanding code context, identifying issues, and generating fixes — and configured them to… write comments asking humans to implement the fixes.
We gave artificial intelligence the ability to read code, understand intent, and produce solutions. Then we told it to be a backseat driver.
“This function is too long. Consider breaking it into smaller pieces.” “This variable name could be more descriptive.” “This duplicate code could be extracted into a helper function.”
The AI can see the problem. The AI can propose the solution. The AI can write the code. But the AI has been configured to stop at the “giving advice” stage, like a personal trainer who tells you to lift weights but refuses to let you into the gym.
The better way: If your AI can identify an issue and propose a fix, have it actually make the fix. Tools like Claude Code can run in CI pipelines and commit fixes directly to branches — the AI doesn’t just identify the problem, it solves it. You review what it did rather than transcribing what it suggested.
If you’re not ready for autonomous fixes, at minimum use the suggestion feature that both GitLab and GitHub provide — format your AI’s proposed changes as suggestion blocks so developers can accept them with a single click rather than manually copying code from a comment into their editor. The difference between a comment saying “consider renaming this variable” and a suggestion block that applies the rename when clicked is the difference between creating work and doing work.
The Root Cause: We’ve Automated the Easy Part
Here’s the pattern I keep seeing: teams automate the detection and communication of problems, then leave the resolution to humans. But detection is often the easy part. The hard part — the part we should be automating — is the fix.
Consider what we’re actually doing when we deploy a bot that comments “please bump the version number”:
We’ve written code to analyse the merge requestWe’ve integrated with the API to post commentsWe’ve deployed and maintained infrastructure to run this automationWe’ve established notification systems so developers see the commentsAll of this effort, and the outcome is… typing a message that a human must act on. We’ve built a Rube Goldberg machine for generating to-do items.
The economist John Kenneth Galbraith noted that “faced with the choice between changing one’s mind and proving that there is no need to do so, almost everyone gets busy on the proof.” In engineering, faced with the choice between automating a task completely and automating just enough to feel productive, we often choose the latter.
A Defense of the Indefensible (That Isn’t Actually a Defense)
Now, I need to pause here and say something important: the people building these systems aren’t doing anything wrong. They’re not lazy, they’re not incompetent, and they’re certainly not malicious.
They’re doing exactly what seems reasonable given the tools and knowledge available to them. Code review bots are marketed as tools for posting comments. CI/CD tutorials focus on running checks and reporting results. The documentation for these systems primarily describes how to analyse and communicate, not how to take action.
If you’ve never seen automation that actually fixes things, “automation that tells you what to fix” looks like automation. It’s only when you step back and compare it to what’s possible that the absurdity becomes clear.
This is why education matters more than criticism. Every engineer who learns to configure a bot to leave a “please bump the version” comment is one configuration file away from automating the version bump itself. They’ve already done 80% of the work. They just need someone to show them the last 20%.
And here’s the uncomfortable truth: if we don’t teach this better approach, the “commenting bot” pattern will propagate. New engineers will see it, assume it’s best practice, and replicate it. The anti-pattern will spread not through any failure of character but through simple observation of what appears to be working and appears to be “best practice” (another post entirely for that phrase).
The Bottom Line
We’ve built an impressive infrastructure for making computers ask humans to do things. What we haven’t done, in many cases, is build infrastructure for computers to actually do things.
The automation anti-pattern isn’t about bad intentions or poor engineering. It’s about stopping one step too early — building the detection and communication layer but not the action layer. It’s about confusing “automated notification” with “automated solution.”
As the architect Buckminster Fuller observed, “You never change things by fighting the existing reality. To change something, build a new model that makes the existing model obsolete.” We don’t need to criticise the bots that leave comments asking for manual work. We need to show people how to build bots that do the work themselves.
The next time you’re configuring a CI check or a code review bot, ask yourself: am I automating a solution, or am I automating a request for someone else to implement one? Am I building a tool, or am I building a very sophisticated way to generate interruptions?
The difference between automation and delegation is who does the work. If a computer is telling a human to do something a computer could do, that’s not automation. That’s just spam with extra steps.
Now, if you’ll excuse me, I need to go review a merge request. Apparently there’s a comment thread with seventeen unresolved items telling me to run a command that the bot could have run itself.