
Please Stop Asking AI to Count Your Tabs
Or: Why Your LLM Is the Most Expensive Linter in History
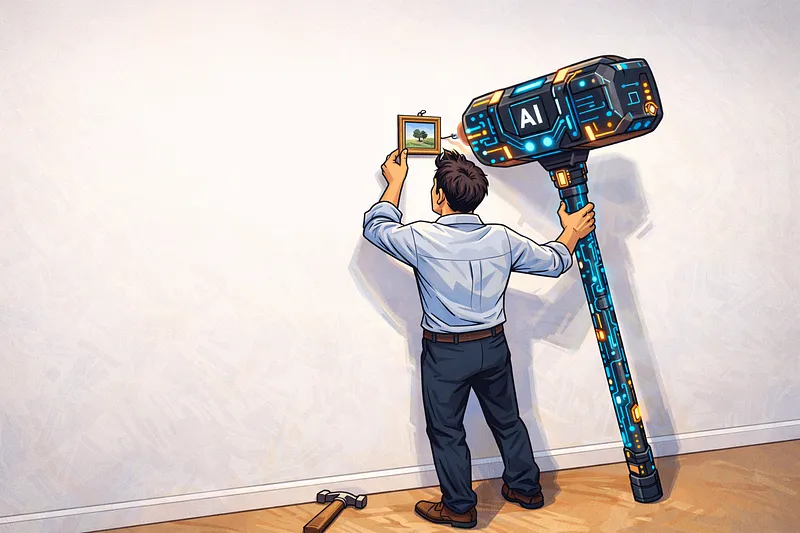
There’s a principle in engineering that we’ve somehow forgotten in the rush to sprinkle AI on everything: use the right tool for the job. You wouldn’t use a sledgehammer to hang a picture frame. You wouldn’t hire a Michelin-star chef to make toast. And yet, across engineering organisations worldwide, we’re burning GPU cycles and inference costs to do what a regex could handle in milliseconds.
As the economist Thomas Sowell observed, “There are no solutions, only trade-offs.” But here’s the thing — sometimes there are solutions. Sometimes the solution has existed for twenty years, is deterministic, runs in your CI pipeline for free, and doesn’t hallucinate. We’ve just chosen to ignore it because AI is shinier.
I’ve spent the last few months auditing how teams are using our AI code review tooling. What I found was both impressive and deeply concerning. We’ve built genuinely useful AI capabilities for complex code analysis. And then we’ve also configured it to check if enum names are PascalCase.
The Archaeology of Bad Decisions
Let me walk you through what I discovered. Across dozens of repositories, I found AI prompts configured to catch things like:
Naming convention violations (camelCase vs PascalCase)Magic numbers in codeMissing documentation commentsTODO comments in new codeInline styles in React componentsImproper list keys in JSXLong methodsExcessive nestingYou know what all of these have in common? Static analysis tools have been catching them since before some of your junior developers were born. ESLint. Detekt. Scalastyle. SwiftLint. These aren’t obscure academic projects — they’re battle-tested, deterministic, and infinitely cheaper than asking an LLM to squint at your code.
The React hooks rules one particularly pains me. Facebook literally created eslint-plugin-react-hooks specifically because they knew the rules of hooks are subtle enough that humans will mess them up. It's been maintained for years. It's free. It runs in milliseconds. But apparently, we'd rather pay for an LLM to maybe catch it, sometimes, when it's feeling cooperative.
The Consistency Problem Nobody Wants to Discuss
Here’s the dirty secret about using LLMs for code review: they’re not consistent. You can try to make them more consistent — tweaking prompts, adding guardrails, chaining agents together. But every one of those improvements comes with a cost, both literal and computational. And you’re still fighting against the fundamental nature of probabilistic models.
The physicist Richard Feynman once said, “The first principle is that you must not fool yourself — and you are the easiest person to fool.” We’ve fooled ourselves into thinking AI consistency is a solvable prompt engineering problem. It’s not. It’s a fundamental characteristic of the technology. That’s not to mean we should give up on it, but we should know when to and not to use it.
Meanwhile, a linting rule either fires or it doesn’t. Every time. On every machine. In every CI run. There’s no “well, Chat GPT was having an off day” explanation to give your team when the same violation slips through that it caught last week.
I reviewed configurations where teams had AI checking for architecture layer violations — ensuring service layers don’t directly access repositories, that kind of thing. ArchUnit has been doing this deterministically since 2017. You write the rule once, and it enforces your architecture forever. No prompt tuning. No temperature adjustments. No wondering if today’s model update broke your guardrails.
The Irony That Hurts the Most
What really gets me is this: I’ve seen teams configure AI to detect problems but not fix them. They’re paying for inference to have an LLM say “hey, you should use PascalCase for that enum” without actually fixing it.
Let that sink in.
We’ve taken a technology capable of complex reasoning and creative problem-solving and reduced it to a very expensive, inconsistent, sometimes-wrong suggestion bot for problems that have had automated fixes for decades. Scalastyle won’t just tell you your naming is wrong — it can be configured with auto-formatting that fixes it. ESLint with --fix will correct your React keys and hook dependencies automatically.
This is like buying a Formula 1 car and using it exclusively to check if your garage door is closed. The car could do so much more, but we’ve limited it to the world’s most overqualified sensor.
What AI Should Actually Be Doing
Here’s where I’ll offer some redemption. AI isn’t useless for code review — far from it. But we need to be honest about where it adds value versus where we’re just showing off our shiny new hammer.
AI excels at things that require understanding context, intent, and subtle patterns that can’t be captured in a regex. Things like:
Detecting logical errors that compile but don’t make senseIdentifying potential race conditions or security vulnerabilities that require understanding data flowSuggesting architectural improvements based on understanding the broader systemCatching business logic mistakes that require domain knowledgeReviewing complex algorithms for correctnessYou know what AI shouldn’t be doing? Counting spaces. Checking if your variable starts with a capital letter. Verifying that your imports are in alphabetical order.
The Meta-Solution You’re Missing
Here’s the real insight that I wish more engineers would internalise: if you’re going to use AI, use it to write the automation, not to be the automation.
I put together a demonstration of exactly this approach for a code migration project. The task was migrating from NUnit assertions to Shouldly across a large codebase. The obvious approach would be to throw AI at the code and ask it to update the assertions. And it would work… mostly. Sometimes. With varying degrees of consistency that you’d need to manually verify anyway.
Instead, I used AI to write Roslyn analyzers and code fixes. The AI helped generate the metaprogramming code — the rules and transformations — which I could then unit test to ensure consistency. Once verified, those analyzers ran across the entire codebase deterministically. Same transformation, every time, guaranteed.
You can watch the full walkthrough here:
The key insight is this: AI is brilliant at understanding patterns and generating complex code. Use that brilliance to create tools that are deterministic, testable, and consistent. Don’t use AI as a runtime reviewer when you can use it as a compile-time tool generator.
Think about what this means for those linting rules I found in our AI configurations. Instead of asking AI to check for O(n²) list operations in every code review, use AI to help you write a Scalafix rule that catches them automatically. Instead of burning inference costs on every PR to check for magic numbers, spend thirty minutes with an LLM to configure Detekt properly.
The Bash Script Test
Before you configure any AI check, ask yourself this question: could this be a bash script?
I’ve reviewed CI configurations and even IDE automation commands that were essentially AI wrappers around what could have been ten lines of shell. Checking file naming conventions? That’s a find command with a regex. Ensuring configuration values are quoted? yamllint has a rule for that. Validating that test files follow a naming pattern? Grep. Literally just grep.
And if you genuinely don’t like writing bash — which is fair, bash is lovecraftian horror pretending to be a scripting language — then use AI to write the bash script for you. Ask it once, get a script you can run forever, and move on with your life. Every engineer should do themselves a favour and learn PowerShell instead, but that’s a blog post for another day.
The problem isn’t that engineers are using AI. The problem is that they’re using AI as a substitute for thinking about what the right tool actually is. And often the right tool is boring, deterministic, and decades old.
A Field Guide to Not Wasting Money
Let me give you a practical framework. When you’re tempted to add an AI check to your code review process, run through this decision tree:
Is it a pattern that can be expressed as a rule? If yes, there’s almost certainly a static analysis tool that handles it. ESLint for JavaScript. Detekt for Kotlin. Scalastyle, Scalafix, or WartRemover for Scala. SwiftLint for Swift. The list goes on. These tools exist because the problem is solved.
Is it about code structure or architecture? ArchUnit can express architectural constraints as tests. “Services should not depend on controllers.” “Only classes in package X should access package Y.” These are deterministic, version-controlled, and infinitely more reliable than hoping your AI prompt captures the nuance.
Is it a migration or transformation? Use AI to write the transformation tool, not to perform the transformation. Codemods, Roslyn analyzers, Scalafix rules — these are your friends. AI is excellent at helping you write them. AI is mediocre at consistently applying them at scale.
Does it genuinely require understanding intent and context? Now you’re in AI territory. Does this function actually do what the ticket says it should? Is this the right approach architecturally given our long-term plans? These questions require the kind of reasoning that justifies the cost and accepts the occasional inconsistency.
The Cost Nobody Calculates
Let’s talk about what this misuse actually costs. I’m not just talking about API bills, though those add up fast when you’re running inference on every pull request.
The real cost is trust degradation. When your AI review bot flags something incorrectly — or misses something it caught last week — engineers start ignoring it. The signal-to-noise ratio collapses. Soon, AI comments are the new compiler warnings: technically present, universally dismissed.
Compare this to a linting rule. It either fires or it doesn’t. Engineers learn to trust it. When it flags something, they fix it without the mental overhead of wondering if the bot is confused today. That trust is worth more than any feature flag or configuration parameter.
As the management thinker Peter Drucker noted, “Efficiency is doing things right; effectiveness is doing the right things.” We’ve become remarkably efficient at applying AI to problems. We’ve become rather ineffective at asking whether AI is the right solution.
The Uncomfortable Questions
Let me leave you with some questions to take back to your team:
How much are you spending on AI inference for checks that could be static analysis rules? Have you actually done the maths?
Or better yet, ask an LLM to analyse your Code review instructions for you AI reviewer for things that could be static code analysis.
The Bottom Line
AI is a remarkable technology. It can reason about code in ways that were science fiction a decade ago. It can help us write better software, understand complex systems, and automate genuinely difficult tasks.
But we’re not using it for any of that when we ask it to check if our enums are PascalCase.
We’ve taken the most powerful text understanding technology ever created and turned it into a spectacularly expensive replacement for grep. We’ve built the engineering equivalent of using a helicopter to go to the corner shop — technically possible, impressively expensive, and deeply unnecessary.
The solution isn’t to stop using AI. It’s to start using it for what it’s actually good at. Use it to write your linting rules. Use it to generate your code transformations. Use it to understand complex patterns and suggest architectural improvements. Use it for the hard problems that require reasoning about intent and context.
And for the love of all that is deterministic, let your linting tools handle the tabs versus spaces debate. They’ve been doing it reliably for longer than some of your interns have been alive.
Now, if you’ll excuse me, I need to go review some AI configurations. Apparently, we’ve got a prompt somewhere that’s checking for trailing whitespace, and I have a .editorconfig file to write.