
The Inner Loop Nobody Measures
Or: Why Your Production Monitoring Is Excellent and Your Developer Experience Is a Black Box
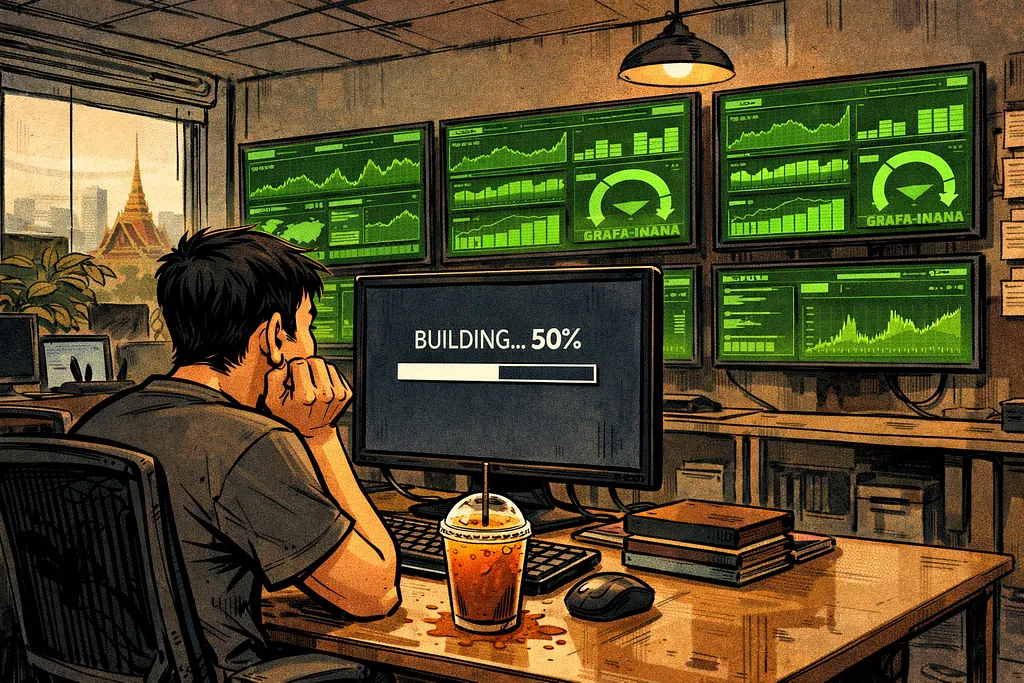
The sound wasn’t there anymore. That’s what he noticed first.
It was 10:23 on a Wednesday morning, and Somchai had pressed debug in Visual Studio, and the keyboard had gone quiet. The kind of quiet where your fingers are still hovering over the keys, not quite ready to let go of the idea that something might happen quickly. The build progress bar crept forward. The fan on the laptop started working harder than the conversation he was about to have with the code. He opened Slack. Read a thread. Closed it. The browser still wasn’t up. He pulled his Thai iced tea closer, the condensation already pooling on the vinyl floor beside his desk, and stared at the loading indicator with the particular thousand-yard look of someone who has been here before, recently, and will be here again this afternoon.
Nobody filed a ticket about it. There was no incident. The dashboards on level 6 were green. Standup had been fine. And somewhere, quietly, every developer on the team had developed a private protocol — their own small rituals to fill the dead time between pressing a key and seeing a result.
Here’s the uncomfortable truth: you are measuring the wrong thing. Almost certainly. And the gap between what you’re measuring and what your engineers actually experience every day is not a rounding error. It’s where the real cost of developer productivity disappears.
The Outer Loop Has Excellent Monitoring
We have genuinely gotten good at measuring what ships. DORA metrics and similar — deployment frequency, lead time for changes, Build time in CI, change failure rate, mean time to recovery — are well understood, increasingly instrumented, and legitimately useful. If you’re not tracking them, start. They are a reasonable proxy for organisational health and a good place to begin the conversation about engineering effectiveness.
But here’s what DORA and the others usually measure: the outer loop. The cycle from code committed to code in production. That’s one part of an engineer’s day. In many organisations, it’s not even the biggest part.
The inner loop — write, build, test, see — is where engineers spend most of their working hours. It’s the tight feedback cycle that determines whether a developer is in flow or context-switching into oblivion. And in most organisations, it is a complete black box.
As W. Edwards Deming observed, “If you can’t describe what you are doing as a process, you don’t know what you’re doing.” We’ve described the deployment process in careful detail and built excellent tooling to measure it. We’ve left the development process — the hours of actual engineering work that precede every PR — almost entirely undescribed.
A Metric That Was Right About the Wrong Thing
We had compile metrics. We were genuinely proud of them. Around 30 seconds at P75 for a non-trivial .NET service — that’s a decent build, I didn't believe it, people wouldn't complain if it was that good. I sat down with Somchai and asked him how it felt.
“When you press debug in Visual Studio and wait for the browser to come up — does that usually take about 30 seconds?”
He laughed. Not a polite laugh. The kind of laugh that means the question was almost charmingly naïve.
“Nooo,” he said. “About five minutes.”
I stared at him.
“But the build is only thirty seconds.”
He shrugged in that particular way that meant: yes, and?
He was right. The build was thirty seconds. The compile metric was accurate. It was also measuring one link in a much longer chain: compile → startup → prewarm → browser ready. The service was loading real data from QA servers in the data centre at startup — database warm-up, cache population, dependency initialisation. All of it legitimate. None of it visible in our build metrics. The compile finished in 30 seconds. The service wasn’t usable for another four and a half minutes.
Because nobody had measured that gap, nobody knew it existed. And nobody knew it existed for every developer, every morning, every debug cycle.
This is what makes inner loop blindness particularly insidious: the metric wasn’t wrong. It was just measuring the wrong question. We were asking “how long does it take to compile?” when the question engineers were silently answering every day was “how long before I can actually see my changes?”
The Chain Nobody Draws
The inner loop is not a single event. It’s a chain, and every link can degrade independently.
For a backend service change, the chain looks something like this:
compile → startup → prewarm / first request → browser ready
For a frontend change:
save → HMR → browser update
For a test run:
trigger → fixture spin-up → execution → result
Most engineering organisations measure exactly one of these links in exactly one environment: CI build time. That’s the outer edge of the chain, run in a clean, well-resourced environment, on hardware nobody actually develops on day-to-day.
When HMR degrades from 200ms to 3000ms over three months of dependency additions, no CI metric catches it. When test suites become too slow to run locally, engineers stop running them — and CI stays green while the inner loop silently breaks. When startup time drifts from 30 seconds to five minutes because of a web server prewarm routine added three sprints ago, nobody files a ticket because nobody has a number to compare against. And its never 30 seconds it 5 minutes in 1 day, its slowly, over time.
Degradation without a baseline is just how it is now. Engineers adapt. They develop workarounds. They open Slack. They make another Thai iced tea. And the aggregate cost of those micro-interruptions — across a team of 50, or 200, or 700 — compounds into something that looks, from the outside, like a velocity problem with no obvious cause.
John Wooden, who spent decades coaching elite athletes, put it plainly: “It’s the little details that are vital. Little things make big things happen.” He was talking about basketball. He might as well have been talking about the 2 minutes of context-switching that happens every time a developer’s debug cycle is longer than it needs to be.
Why This Is Harder to See Than You Think
Production monitoring exists because production problems have visible consequences. Something goes down, something slows down, customers complain, revenue drops. The feedback loop is tight and the motivation to instrument it is obvious.
Inner loop degradation has none of those properties. It’s diffuse. It accumulates slowly. The cost manifests as slightly slower PR submission rates, slightly more context switching, slightly less willingness to run the full test suite before pushing. No alert fires. No dashboard turns red. Engineers adapt, rationally, to the environment they’re in — and the environment gets quietly worse.
There’s a structural problem too. The team that owns the monitoring platform is not the team that feels the pain of a slow debug cycle. Platform teams are incentivised to measure what they can control. What they can control is CI infrastructure, deployment pipelines, production observability. What they often cannot see is what happens on the developer’s laptop between the moment they start writing code and the moment they open a PR.
The same failure mode shows up in web performance — a centralised team owns the metric but isn’t the team that feels the consequence. The fix is the same: make the data visible to the teams who live with it, and give them the tools to act on it. You built it, you run it, you should own what your inner loop actually looks like. The platform team is here to help you, but they aren’t going to do the work for you, that’s on you.
The One That Got Away
Here’s the version of this problem that should keep you up at night: you don’t know what you’re missing.
Somchai knew his debug cycle was slow. He’d adapted to it. It was just how things were. The five minutes weren’t unusual to him because there was no comparison — no data showing that the rest of the team was seeing something different, no baseline that said “this used to be faster.” The metric gap didn’t just hide the problem from us. It hid it from the people experiencing it, because without a number to point at, slow becomes normal.
This is the failure mode that’s hardest to recover from. Not the fire that sets off alarms, but the slow drift that everyone adjusts to until nobody remembers what fast felt like.
The inner loop is where engineers live. It’s where flow happens or doesn’t. It’s where the best engineers on your team either find their rhythm or spend their afternoon watching progress bars. And until you measure it — all of it, not just the link that’s easiest to instrument — you’re operating on anecdote and intuition while calling it engineering.
What Comes Next
So what would you actually measure? And more importantly — what would you find that you weren’t looking for?
In the next post, we get specific: what we actually instrumented across .NET, JavaScript, and JVM stacks, how the collection works with zero friction for engineers, and what the data surfaced that had nothing to do with code. One finding involved three engineers, a webpack build, and hardware we didn’t know needed replacing. Another involved a test suite that was technically green in CI and functionally abandoned in practice.
Post 2: What We Actually Instrumented — and What We Found — coming next.
And if you want to skip straight to the tool that makes all of this possible, Post 3: Introducing Agoda.DevExTelemetry covers the open-source dashboard and exactly how to get your own data flowing.
Further Reading
If you’re building the case internally for investing in inner loop observability, these are worth having in your back pocket:
- The DevEx Framework from the ACM Queue — feedback loops, flow state, and cognitive load as the three pillars of developer experience- Accelerate (Forsgren, Humble, Kim) — the DORA research. Good starting point for the outer loop argument; the inner loop argument is what comes after- The companion posts this series builds on: Bridging Worlds: Making .NET BFF and React/Vite Play Nice in Development — the development setup we ended up instrumenting; Semantic Monitoring: The Question You’re Not Asking About Your Production Systems — the same philosophy applied to production; Mesh Programming: Where Visual Design Meets Synchronized Development — why inner loop speed directly affects collaborative design-engineering workflows; The Impact of Paved Paths and Embracing the Future of Development and Starting a Paved Path with .NET Templates — where telemetry clients belong in the paved path from day one